
DbContext pooling, enabled with AddDbContextPool, keeps a pool of DbContext instances and rents one per scope instead of constructing a new one, then resets it and returns it at scope end.
It helps on high-RPS endpoints where the work per context is tiny, and it is a rounding error where the database round trip dominates.
It bites when your context carries custom state, which the pool does not reset.
Every request in a typical ASP.NET Core app constructs a DbContext, uses it for a handful of queries, and throws it away.
Construction is not free: EF Core sets up the change tracker, the service scope, and per-instance state, and disposal tears it down.
AddDbContextPool skips that churn by recycling instances.
The switch is a one-word edit that also changes the lifecycle rules of your context.
Code that was fine with AddDbContext can start leaking state across requests.
What Pooling Changes
The registration looks almost identical:
builder.Services.AddDbContextPool<AppDbContext>(options =>
    options.UseNpgsql(builder.Configuration.GetConnectionString("Database")));
With plain AddDbContext, each scope constructs a new context and disposes it at scope end.
With pooling, "dispose" becomes "reset and return to pool", and "construct" becomes "rent from pool if one is available".
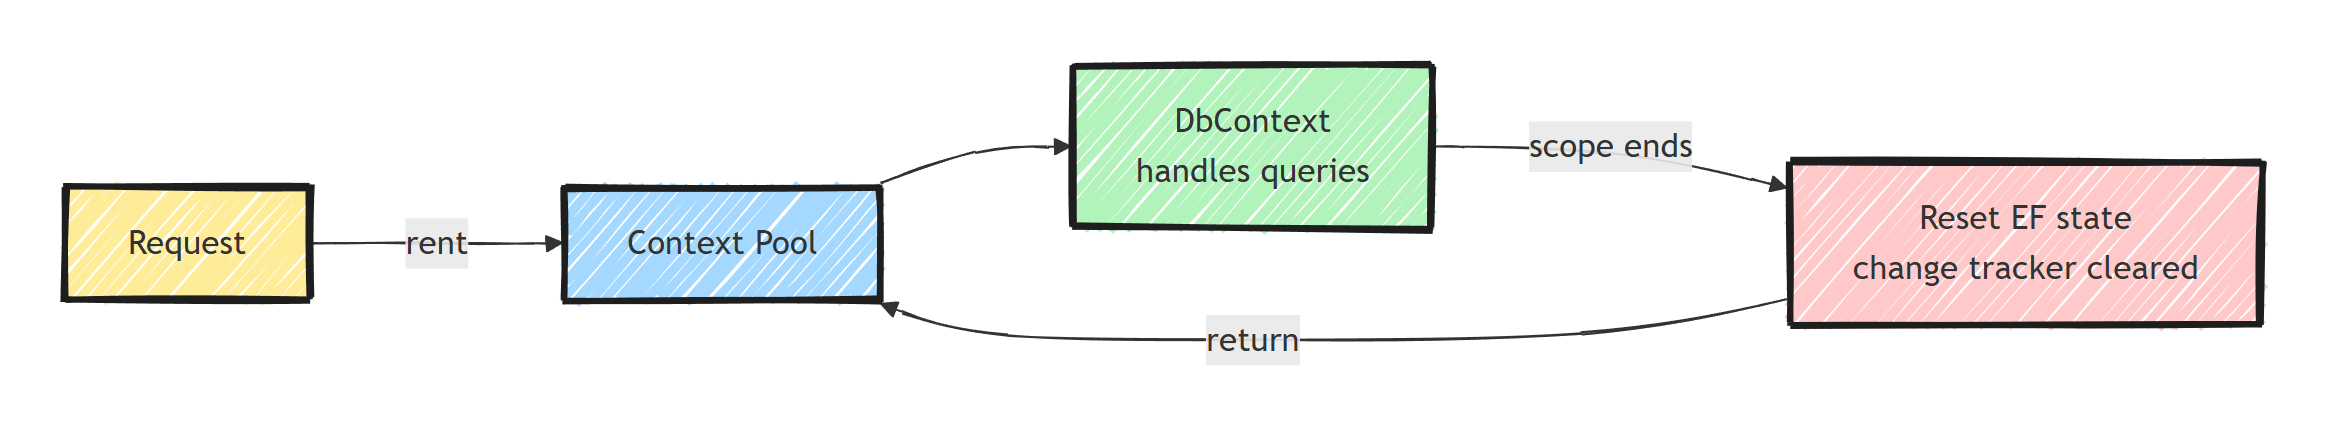
The reset clears EF Core's internal state: the change tracker is emptied, connection state is handled, and the context is as good as new from EF Core's perspective.
Fields you add to your own DbContext subclass are not reset.
The default pool size is 1024.
Under burst load beyond that, extra contexts are created and disposed instead of pooled, so the pool never becomes a bottleneck or a queue.
You can tune it with the second argument to AddDbContextPool, but change the default only after measuring pool saturation and allocation pressure.
Do not confuse context pooling with connection pooling. ADO.NET connection pooling happens a layer below and is on by default; a non-pooled context still reuses pooled database connections. For the Npgsql side of that story, see NpgsqlDataSource and connection pooling.
Is DbContext Pooling Worth It?
Pooling removes per-request allocation and setup of the context graph. The EF team's own benchmarks show it matters most when the work per context is tiny: high-RPS endpoints running one cheap indexed query. In those scenarios the requests-per-second improvement is material, but the result depends on how much work surrounds each context.
In a typical business app, the database round trip costs a few milliseconds and dominates the microseconds saved on construction. There, pooling is a rounding error.
My rule: pooling is a legitimate optimization for hot, simple endpoints, and harmless elsewhere if your context is stateless. Measure with BenchmarkDotNet or a load test before crediting it with anything.
Bite 1: State on the Context Leaks Across Requests
This is the big one.
The pool resets what EF Core knows about, and nothing else.
Any field you added to your DbContext subclass survives into the next request:
public class AppDbContext(DbContextOptions<AppDbContext> options)
    : DbContext(options)
{
    // DANGER with pooling: this survives the reset
    public Guid TenantId { get; set; }

    protected override void OnModelCreating(ModelBuilder modelBuilder)
    {
        modelBuilder.Entity<Order>()
            .HasQueryFilter(o => o.TenantId == TenantId);
    }
}
With AddDbContext, this pattern works: each request gets a fresh context, middleware sets TenantId, the global query filter does its job.
With AddDbContextPool, request B rents the context request A used.
If B's middleware fails to set TenantId, B queries A's tenant data without any error.
That is a data breach.
If you pool a stateful context, the state must be set unconditionally on every rental. And because a pooled context cannot inject scoped services (the next bite), the assignment has to happen after the rental. The safe pattern is middleware that resolves the scoped context, which rents it from the pool, and assigns the value before any handler runs a query:
// Middleware, runs on every request without exception
app.Use(async (httpContext, next) =>
{
    var db = httpContext.RequestServices
        .GetRequiredService<AppDbContext>();

    // Always assign, even when the request has no tenant
    db.TenantId = ResolveTenant(httpContext);

    await next();
});
Multi-tenancy is the most common place this trap appears, and the tenant-per-request patterns from multi-tenant applications with EF Core need this exact adjustment before they are pool-safe.
Bite 2: The Constructor Contract
A pooled context should expose a single public constructor that takes only DbContextOptions<T>.
The pool constructs instances itself, outside any request scope, so it cannot supply request-scoped dependencies.
Since EF Core 8 it resolves extra constructor parameters from the root service provider, which only suits singletons:
// Works with AddDbContext. With AddDbContextPool, a scoped ICurrentUser throws on first use
// when scope validation is on, and is shared by every request when it is off
public class AppDbContext(
    DbContextOptions<AppDbContext> options,
    ICurrentUser currentUser) : DbContext(options)
{
}
If your context injects the current user for audit logging, or a tenant service, pooling forces a redesign: move the dependency out of the constructor and into an interceptor resolved from DI, or set it post-rental as shown above.
Interceptors registered via options.AddInterceptors in the pooled options are shared singletons, so they must be stateless too.
Bite 3: Long-Lived Rentals Poison the Pool
The pool assumes short rentals. A context held for the length of a background job, or one that tracked ten thousand entities, gets its change tracker cleared on return, but the internal structures may have grown, and while it is held, it is not available.
Two related mistakes:
- Injecting a pooled context into a singleton hosted service. The context is rented once and never returned. Use
IDbContextFactory<T>instead, and there is a pooled variant:
builder.Services.AddPooledDbContextFactory<AppDbContext>(options =>
    options.UseNpgsql(connectionString));

public class OrderSyncJob(IDbContextFactory<AppDbContext> factory)
    : BackgroundService
{
    protected override async Task ExecuteAsync(CancellationToken ct)
    {
        while (!ct.IsCancellationRequested)
        {
            await using var context = await factory.CreateDbContextAsync(ct);
            // short-lived unit of work, context returns to pool on dispose
        }
    }
}
- Treating the pooled context as a cache because "it sticks around". The change tracker is wiped on every return, while your own fields keep their values.
My Recommendation
- Context has no custom state and no request-varying dependencies: pooling is low risk, but still measure it on the target workload.
- Context carries per-request state (tenant, user, soft-delete toggles): pool only after making the assignment unconditional on every rental, and add a test that hammers two tenants concurrently and asserts isolation.
- Background services:
AddPooledDbContextFactory, one context per unit of work. - Low-traffic apps: skip it, since the construction savings are negligible and the lifecycle rules still apply.
For more context lifetime guidance, see DbContext configuration best practices.
Summary
AddDbContextPool recycles context instances, trading construction cost for stricter lifecycle rules.
The pool resets EF Core's state, not yours: custom fields survive across requests, constructors cannot take request-scoped services, and singletons that hold a rental never return it to the pool.
The performance win is concentrated in hot endpoints where per-request query work is tiny. Leaked tenant or user state on a reused context is a correctness bug that only shows up once requests from more than one tenant or user hit the app.
Before you pool a stateful context, make sure that state is assigned unconditionally on every rental.
Frequently Asked Questions
What does AddDbContextPool do in EF Core?
It maintains a pool of DbContext instances. When a request needs a context it rents one from the pool instead of constructing it, and when the scope ends the context is reset and returned to the pool instead of being disposed.
Is DbContext pooling worth it?
It removes context construction and disposal overhead, which is measurable on hot paths with high request rates and cheap queries. For typical apps where database I/O dominates, the gain is small. Benchmark your own workload before deciding.
Why is my data leaking between requests with DbContext pooling?
The pool resets EF Core internal state like the change tracker, but it cannot reset fields you added to your DbContext subclass. Any custom field, like a tenant id, keeps its value from the previous request unless you reset it explicitly.
Can I use constructor injection of scoped services with a pooled DbContext?
No. The pool creates contexts outside any request scope, so a pooled context should have a single constructor accepting only DbContextOptions. To flow per-request state like the current tenant or user into a pooled context, set it after renting the context, typically from middleware that assigns it on every request.
What is the default pool size for DbContext pooling?
The default maximum pool size is 1024 contexts. If all are in use, additional contexts are created normally and disposed instead of returned, so the pool never blocks.


