
Yes, pg_dump takes a shared lock on every table it dumps and keeps it until the dump ends.
Reads and writes keep running, and schema changes wait.
A queued ALTER TABLE also makes later queries on that table wait for the rest of the dump, and lock_timeout caps that stall.
I ran this on November 7, 2026, with PostgreSQL 18.6 in Docker containers under WSL2, not on a real VPS.
The timing runs used 29 GB of pgbench data on a shared disk, and a second pass held the dump open so I could choose when it ended.
The .NET runs used EF Core 10.0.14 and Npgsql 10.0.3, and I didn't test pg_dump -j, many tables, or a connection pooler.
What Lock Does pg_dump Take?
pg_dump takes one mode, ACCESS SHARE, on every table in the dump.
Per the lock docs, that mode conflicts only with ACCESS EXCLUSIVE, which many ALTER TABLE forms, DROP TABLE, and TRUNCATE need.
The dump keeps each lock until it finishes, so it still held a 1000-row orders table, already copied, while it worked through pgbench_accounts.
Does pg_dump Block Reads and Writes?
No.
During a dump, a fresh psql running SELECT, INSERT, UPDATE, or DELETE took 0.032 to 0.093 s including the connection, against 0.030 to 0.042 s with no dump.
No transaction failed in any run.
The dump still costs something. With a 307 MB database on tmpfs, dumps looping, and everything squeezed into one Docker CPU, TPS held at a fixed 150 but p99 went from about 2 ms to about 60 ms, at least partly from Docker's CPU quota, and I didn't test a 1 vCPU VPS or a real disk.
Is a Dump Consistent While Writes Continue?
Yes.
The dump reads from one snapshot, so the restored copy holds the database as of the moment the dump started.
pgbench transactions add the same amount to an account, a teller, a branch, and a history row, so those totals must agree, and I restored three dumps taken during writes at 300 TPS:
| Run | History rows before dump | Restored | History rows after dump |
|---|---|---|---|
| 1 | 253257 | 253372 | 270017 |
| 2 | 271803 | 271835 | 289072 |
| 3 | 290883 | 290983 | 307949 |
The totals agreed in every restored copy, and dumping the tables one at a time during the same writes broke them in all 3 runs. Live counts move past the dump, so on a busy database, a restore test can't compare with a live count taken earlier. Counts taken on the dump's own exported snapshot matched the restored copy exactly in 3 of 3 runs, and counts taken just before it didn't.
Why Do Queries Hang When a Migration Runs During a Dump?
Adding a column needs ACCESS EXCLUSIVE, which conflicts with the dump's lock, so the ALTER TABLE waits.
A later SELECT only needs ACCESS SHARE, but it queues behind the waiting ALTER.
This query shows the chain (shop-postgres-1 is a placeholder, so use your container):
docker exec shop-postgres-1 psql -U shop -d shop -c "
SELECT pid, application_name, wait_event_type, pg_blocking_pids(pid) AS blocked_by, left(query, 50) AS query
FROM pg_stat_activity
WHERE datname = 'shop' AND pid <> pg_backend_pid()
ORDER BY query_start;"
  pid  | application_name | wait_event_type | blocked_by |                       query
-------+------------------+-----------------+------------+----------------------------------------------------
 13136 | pg_dump          |                 | {}         | COPY public.pgbench_accounts (aid, bid, abalance,
 13143 | psql             | Lock            | {13136}    | ALTER TABLE orders ADD COLUMN note text
 13150 | psql             | Lock            | {13143}    | SELECT count(*) FROM orders
The SELECT waits on the ALTER, and the ALTER waits on the dump.
I started an ALTER on pgbench_accounts about 15 s into a real dump, with pgbench writing at 100 TPS:
| Dump | ALTER waited | Worst SELECT | Seconds at 0 TPS |
|---|---|---|---|
| 60.3 s | 45.0 s | 44.5 s | 44 |
| 69.7 s | 54.2 s | 53.5 s | 53 |
| 69.3 s | 53.9 s | 53.7 s | 53 |
Probes on another table never stalled, and the same ALTER with no dump took 0.044 to 0.085 s.
Which Commands Wait for a Dump?
I ran each command with lock_timeout = '3s' on 1000-row tables the dump had locked.
| Command | During a dump | Readers behind it |
|---|---|---|
| ALTER TABLE (ADD or RENAME COLUMN), DROP TABLE, DROP INDEX, TRUNCATE, VACUUM FULL | Waits for ACCESS EXCLUSIVE on the table | Stall |
| CREATE INDEX CONCURRENTLY, REINDEX TABLE CONCURRENTLY | Waits on the snapshot of the dump | None |
| CREATE INDEX | Runs | Not measured. The docs say it blocks writes |
| VACUUM, ANALYZE | Runs | Not measured |
| REINDEX TABLE | Runs, because the dump holds no index locks | Blocks readers by itself, with or without a dump |
CREATE INDEX CONCURRENTLY stalled nobody, but a lock_timeout left an invalid index behind in all 3 runs, so keep it out of a blanket timeout.
Retrying then stopped on already exists, and with IF NOT EXISTS it reported success while pg_index.indisvalid stayed false, in 3 of 3 runs each (through psql, not EF).
SET lock_timeout = 0 on that statement waited out the dump and built a valid index, in 1 run.
To repair one, wait for the dump to end, because DROP INDEX queues like an ALTER, then drop and rebuild it.
How Do You Stop a Migration From Stalling Readers?
Keep deploys out of the dump window where you can, and set lock_timeout on the migration's session for when they overlap (the docs advise against setting it in postgresql.conf).
The ALTER then gives up:
  ERROR:  55P03: canceling statement due to lock timeout
  Time: 3000.537 ms (00:03.001)
A reader still waits up to that limit: as long as 2.997 s at 3s, 0.992 s at 1s, and 4.873 s at 5s.
Pick the longest stall you can accept.
The limit applies to each lock separately, per the docs, so a migration needing several locks can wait longer.
A failed ALTER migrated nothing, so retry it after a pause.
Save this as a script, because exit in a pasted loop closes your shell:
#!/usr/bin/env bash
container=shop-postgres-1
attempts=${ATTEMPTS:-10}

for attempt in $(seq 1 "$attempts"); do
  if output=$(docker exec "$container" psql -U shop -d shop -v ON_ERROR_STOP=1 \
    -c "SET lock_timeout = '3s'" \
    -c "ALTER TABLE orders ADD COLUMN note text" 2>&1); then
    echo "attempt $attempt: migrated"
    exit 0
  fi
  echo "$output"
  case "$output" in
    *"canceling statement due to lock timeout"*) ;;
    *) echo "attempt $attempt: not a lock timeout, stopping"; exit 1 ;;
  esac
  echo "attempt $attempt: lock busy, retrying in 15s"
  sleep 15
done

echo "gave up after $attempts attempts"
exit 1
It exits 1 on any other error and when attempts run out, so set ATTEMPTS from your dump length.
How Do You End a Stall That Already Started?
Killing the app doesn't end it, because by default the backend keeps waiting on the lock after its client is gone.
With a psql client killed about 4 s into the wait and a dump held for about 25 s, readers waited up to 23.5 s, and the plain ALTER applied once the dump ended, in 3 of 3 runs.
Inside BEGIN it rolled back instead, after the same stall.
pg_terminate_backend ended the wait in 5 of 5 runs, with no column added.
Stop whatever launched the migration first, because one run with --restart=on-failure queued the ALTER again.
Run the chain query from earlier, and find the row whose blocked_by is the pg_dump pid.
That is the ALTER, or a DO block from an EF script.
Put its pid in place of <pid>, and leave pg_dump alone:
docker exec shop-postgres-1 psql -U shop -d shop -c "SELECT pg_terminate_backend(<pid>);"
Does an EF Core Migration Stall Readers During a Dump?
Not with Migrate(), which failed in a different way.
Per its docs, EF Core 9 and later take a migration lock (I ran version 10), and on Npgsql that lock is a LOCK TABLE on __EFMigrationsHistory.
The dump holds ACCESS SHARE on that table too, so Migrate() queues there and never reaches an ALTER.
Readers of orders didn't stall in any run, and the running instance stayed healthy.
Migrate() waited until the Npgsql default Command Timeout of 30 s, then threw:
2026-11-07T10:36:31.180928293Z       Failed executing DbCommand (30,021ms) [Parameters=[], CommandType='Text', CommandTimeout='30']
2026-11-07T10:36:31.180933844Z       LOCK TABLE "__EFMigrationsHistory" IN ACCESS EXCLUSIVE MODE
This needs a dump with more than the timeout left, because one that ended 10 s after the start let Migrate() wait, apply, and exit 0.
EF takes the lock before it reads the applied migrations, so a restart with nothing to apply failed the same way in all 6 runs.
The exception ends the process only because nothing catches it.
My test app applied migrations before it accepted requests:
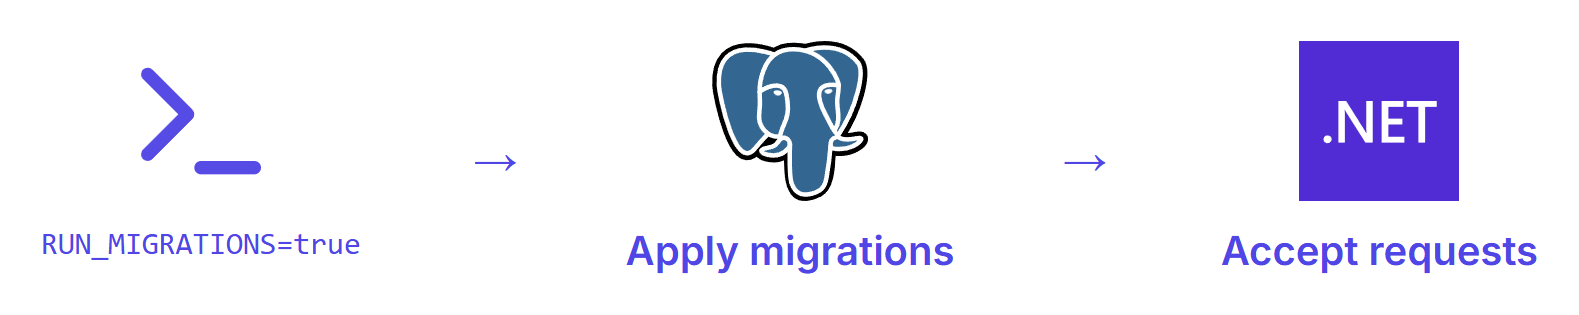
Kestrel wasn't listening yet, so the new container's health check got connection refused during the wait.
When Does a .NET App Get the Stall?
The stall comes back when the ALTER itself reaches the queue, which is what hand-written and script-applied DDL do.
| Path | Stall on orders | Ends when |
|---|---|---|
| App runs a raw ALTER through EF | 29.6, 29.5, 29.5 s | Npgsql timeout, app crashes |
| Idempotent script through psql | 109.8, 116.0, 54.9 s | Dump ends, psql has no timeout |
| Raw ALTER or script with lock_timeout=3s | Up to 3 s | Lock timeout |
With no timeout, the running instance's health check, a SELECT on orders, timed out, and with lock_timeout=3s it stayed healthy.
How Do You Run EF Core Migrations Safely Around a Dump?
Give migrations their own connection string with a lock timeout, passed through Options on a direct connection (I didn't test a pooler).
Host is your app's usual database host, often the Compose service name:
Host=shop-postgres-1;Database=shop;Username=shop;Password=your-password;Application Name=migrator;Options=-c lock_timeout=3s
The timeout alone only fails sooner, at 3,004 ms, and it still ends an unprotected startup. This block asks for pending migrations first, then retries on a lock timeout:
var options = new DbContextOptionsBuilder<ShopDb>()
    .UseNpgsql(migrationConnectionString)
    .Options;
var attempts = 40;
var delay = TimeSpan.FromSeconds(15);

for (var attempt = 1; ; attempt++)
{
    try
    {
        await using var ctx = new ShopDb(options);

        // Migrate() takes its history-table lock even with nothing to apply, so ask first.
        if (!(await ctx.Database.GetPendingMigrationsAsync()).Any())
        {
            break;
        }

        await ctx.Database.MigrateAsync();
        break;
    }
    catch (Exception ex) when (IsLockTimeout(ex) && attempt < attempts)
    {
        await Task.Delay(delay);
    }
}

// EF Core wraps the PostgresException in an InvalidOperationException, so look through inner exceptions.
static bool IsLockTimeout(Exception? ex)
{
    for (; ex is not null; ex = ex.InnerException)
    {
        if (ex is PostgresException { SqlState: PostgresErrorCodes.LockNotAvailable })
        {
            return true;
        }
    }

    return false;
}
With a migration pending and the dump held for 25 s, it migrated on attempt 3 in all 3 runs.
With nothing pending, it exited 0 in about 0.5 s.
The check is itself a read of the history table, so it can queue behind another instance waiting on the lock.
A new container stays unhealthy during the retries, and I didn't test an orchestrator that kills unhealthy containers.
Size attempts from your dump length, because 40 give up after about 12 minutes.
For a script from dotnet ef migrations script --idempotent, set the timeout with PGOPTIONS.
During a dump it exits 3, and the same command exited 0 after it:
docker exec -i -e PGOPTIONS='-c lock_timeout=3s' shop-postgres-1 psql -U shop -d shop -v ON_ERROR_STOP=1 -f - < app/idempotent.sql
What Does pg_dump --lock-wait-timeout Do?
It covers a schema change already holding a lock when the dump starts, and it does nothing about a later ALTER.
With an ALTER transaction open for 30 s, a 1.5 s dump took 29 s, so a stuck transaction hangs the backup, which a backup alert has to catch.
The shell empties appdb.dump before pg_dump runs, so a failed run destroys an earlier file of that name.
Give each run a new name, as my off-site backup script does.
This makes the dump give up:
docker exec shop-postgres-1 pg_dump -Fc -U shop -d shop --lock-wait-timeout=5s > appdb.dump
pg_dump: error: query failed: ERROR: canceling statement due to statement timeout
It exits 1 with a 0 byte file, which a full read rejects.
The error says statement timeout because pg_dump sets statement_timeout around its lock step.
Summary
pg_dump holds ACCESS SHARE on every table until it ends, so reads and writes keep running while schema changes wait.
A queued ALTER held later queries on that table for up to 53.7 s, so set lock_timeout on the migration connection, retry, and keep deploys out of the dump window.
EF Core's Migrate() fails at its own history-table lock at 30 s when the dump has longer left to run, and readers don't stall, while hand-written and script-applied DDL do stall them.
These are container results under WSL2, so check your own dump length against your timeouts on your real server.
My self-hosting course practices off-site Postgres backups and applying migrations before the app accepts requests.
Thanks for reading.
And stay awesome!
Frequently Asked Questions
Does pg_dump lock tables?
Yes. It takes an ACCESS SHARE lock on every table it dumps and holds it until the dump ends. That mode conflicts only with ACCESS EXCLUSIVE, so SELECT, INSERT, UPDATE, and DELETE keep running, while many ALTER TABLE forms, DROP TABLE, and TRUNCATE wait.
Does pg_dump block writes?
No. No transaction failed in any of my runs. A dump still has a cost: with a 307 MB database on tmpfs, dumps looping, and Postgres, the dump, and the load all squeezed into one Docker CPU, throughput held at a fixed 150 transactions per second while p99 latency went from about 2 ms to about 60 ms, at least partly from the Docker CPU quota.
Why do queries hang when a migration runs during pg_dump?
The ALTER TABLE waits for the dump to finish, and every later query on that table queues behind the ALTER. On a real dump, a SELECT waited 44.5 to 53.7 seconds, until the dump ended. Tables the ALTER did not touch stayed fast. Setting lock_timeout on the migration caps the wait.
What lock_timeout should I use for migrations?
Use the longest stall you can accept, because readers wait about that long on every attempt. I measured 1, 3, and 5 seconds, and readers waited about as long as the limit each time. Set it on the migration connection, not server-wide, and retry after a timeout.
Does EF Core Migrate stall readers during pg_dump?
Not in my runs on EF Core 10 with Npgsql. Migrate queues on its own lock on the migrations history table before it reaches any ALTER, so readers of application tables stay fast. If the dump has more than 30 seconds left, it throws at the Npgsql command timeout, even with nothing to apply.
Is a pg_dump consistent while writes continue?
Yes. The whole dump reads from one snapshot, so the restored copy holds one consistent state. In three runs with live writers, the restored totals agreed with each other, while live counts moved past the dump. Separate per-table dumps during the same writes broke those totals in three of three runs.
