A practical way to check a collection for duplicates is to add elements to a HashSet and stop when Add returns false.
Expected time is O(n), with O(n) extra space.
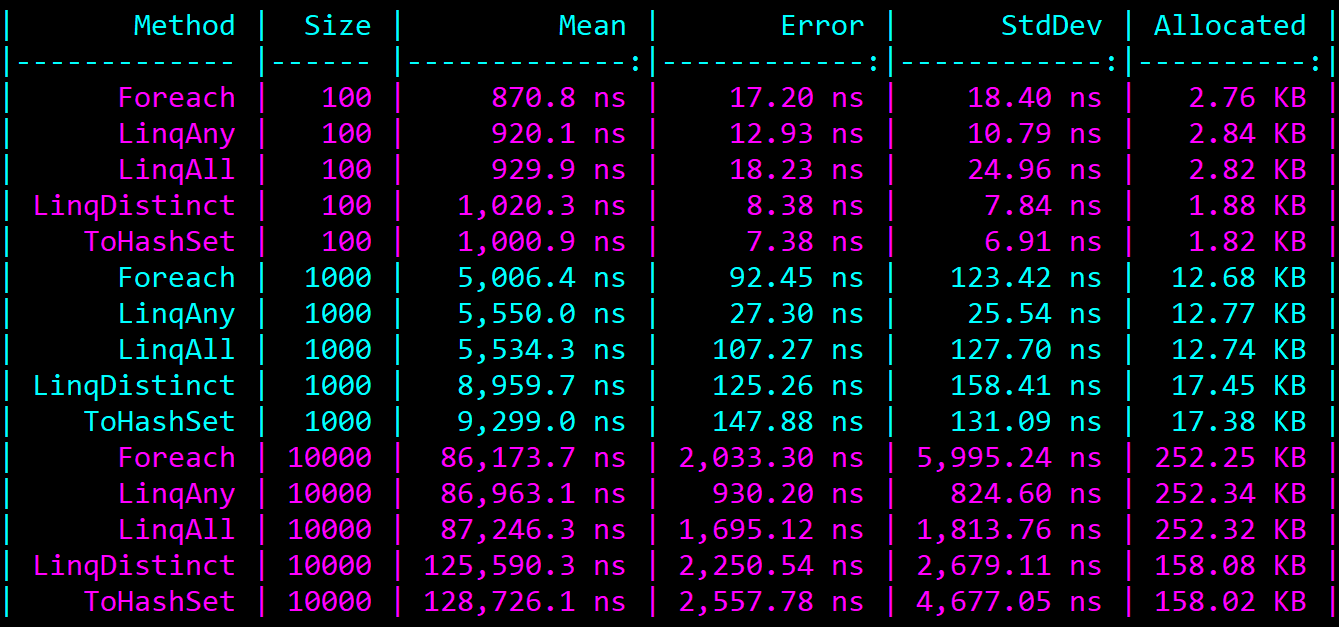
The plain foreach loop had the lowest mean time in these benchmarks; the LINQ Any and All variants use the same early-exit approach.
QuadSpinner Highlighter is an open-source Visual Studio extension that lets you highlight important objects and arbitrary texts to help you navigate your code more easily.
In this week's newsletter, we will take a look at five different ways to check if a collection contains duplicates.
I'm going to explain the idea behind each algorithm, discuss the algorithm complexity (Big O Notation), and at the end, we'll look at some benchmark results.
The five approaches for finding a duplicate will use the:
Let's see how we can implement each approach!
Check For Duplicates With ForEach Loop
The first implementation will use the foreach loop and the HashSet data structure.
Here's the code for the ContainsDuplicates method:
public bool ContainsDuplicates<T>(IEnumerable<T> enumerable)
{
   HashSet<T> set = new();

   foreach(var element in enumerable)
   {
      if (!set.Add(element))
      {
         return true;
      }
   }

   return false;
}
The idea is simple:
- Loop through the collection
- Add each element to the
HashSet - When
HashSet.Addreturns false we found a duplicate - If we loop through the entire collection there are no duplicates
In terms of algorithm complexity, expected time is O(n), assuming well-distributed hashes and constant-time hashing and equality. The set needs up to O(n) extra space, and the loop can stop at the first duplicate.
Adding an element to a HashSet is amortized O(1) under those assumptions.
An individual Add that resizes the set can take O(n).
Check For Duplicates With LINQ Any
We'll combine the idea from the previous implementation of
using the HashSet and pair it with the LINQ Any
method to iterate over the collection.
Here's the implementation for the ContainsDuplicates method:
public bool ContainsDuplicates<T>(IEnumerable<T> enumerable)
{
   HashSet<T> set = new();

   return enumerable.Any(element => !set.Add(element));
}
You can see this implementation is significantly shorter.
But it works the same as the one with the foreach loop.
If any element in the collection satisfies the specified expression,
Any will short-circuit and return true.
Otherwise, it will iterate over the entire collection and return false.
We're still looking at expected linear complexity here, O(n).
Check For Duplicates With LINQ All
For our third implementation, we will use the opposite
of the LINQ Any method - the LINQ All method.
Here's the implementation with LINQ All:
public bool ContainsDuplicates<T>(IEnumerable<T> enumerable)
{
   HashSet<T> set = new();

   return !enumerable.All(set.Add);
}
The idea here is a little different than in the previous implementation.
All will return true if all elements in a collection
satisfy the specified expression.
If at least one element doesn't satisfy the condition -
in our case when a duplicate is found - it will short-circuit and return false.
This is still expected linear complexity, O(n).
Check For Duplicates With LINQ Distinct
So far, we've seen a few implementations using the HashSet data structure.
Now let's consider a different approach.
We can use the LINQ Distinct method to check for duplicates.
Here's the code for the ContainsDuplicates method:
public bool ContainsDuplicates<T>(IEnumerable<T> enumerable)
{
   return enumerable.Distinct().Count() != enumerable.Count();
}
The idea is first find the Distinct elements and Count them,
and then compare that to the number of all elements.
If the number of distinct elements is not equal to the number of all elements, we have a duplicate value.
In terms of algorithm complexity, this is still expected linear complexity.
But Distinct().Count() must inspect the entire input, even if the first two elements are duplicates.
It cannot use the early exit of the previous implementations.
The final Count call can use a stored count for collections such as arrays and lists.
For an enumerable without that shortcut, it enumerates the original input again, so the source must be safe to enumerate repeatedly.
Check For Duplicates With LINQ ToHashSet
For the last implementation we will use the LINQ ToHashSet method.
It takes a collection and creates a HashSet instance from it.
Here's what the ContainsDuplicates implementation looks like:
public bool ContainsDuplicates<T>(IEnumerable<T> enumerable)
{
   return enumerable.ToHashSet().Count != enumerable.Count();
}
We compare the number of elements in the HashSet to the number of elements in the collection.
If they are different, we have a duplicate value.
This is also expected linear complexity, O(n).
Like Distinct, it reads the full input and may enumerate the original source again for Count().
Benchmark Results
Now that we've seen our implementations let's put them to the test.
I ran the benchmark for collections of varying sizes:
- 100
- 1,000
- 10,000
Each integer array contains exactly one duplicate, inserted around 41% of the way through the array. The original benchmark project targets .NET 6 and uses BenchmarkDotNet 0.13.2. The original screenshot does not record the machine or exact runtime version, so these are historical results, not a comparison of current .NET releases.
Here are the results:
| Method | Size | Mean | Error | StdDev | Allocated |
|---|---|---|---|---|---|
| Foreach | 100 | 870.8 ns | 17.20 ns | 18.40 ns | 2.76 KB |
| LinqAny | 100 | 920.1 ns | 12.93 ns | 10.79 ns | 2.84 KB |
| LinqAll | 100 | 929.9 ns | 18.23 ns | 24.96 ns | 2.82 KB |
| LinqDistinct | 100 | 1,020.3 ns | 8.38 ns | 7.84 ns | 1.88 KB |
| ToHashSet | 100 | 1,000.9 ns | 7.38 ns | 6.91 ns | 1.82 KB |
| Foreach | 1000 | 5,006.4 ns | 92.45 ns | 123.42 ns | 12.68 KB |
| LinqAny | 1000 | 5,550.0 ns | 27.30 ns | 25.54 ns | 12.77 KB |
| LinqAll | 1000 | 5,534.3 ns | 107.27 ns | 127.70 ns | 12.74 KB |
| LinqDistinct | 1000 | 8,959.7 ns | 125.26 ns | 158.41 ns | 17.45 KB |
| ToHashSet | 1000 | 9,299.0 ns | 147.88 ns | 131.09 ns | 17.38 KB |
| Foreach | 10000 | 86,173.7 ns | 2,033.30 ns | 5,995.24 ns | 252.25 KB |
| LinqAny | 10000 | 86,963.1 ns | 930.20 ns | 824.60 ns | 252.34 KB |
| LinqAll | 10000 | 87,246.3 ns | 1,695.12 ns | 1,813.76 ns | 252.32 KB |
| LinqDistinct | 10000 | 125,590.3 ns | 2,250.54 ns | 2,679.11 ns | 158.08 KB |
| ToHashSet | 10000 | 128,726.1 ns | 2,557.78 ns | 4,677.05 ns | 158.02 KB |
These values are transcribed from the original benchmark screenshot.
The foreach loop has the lowest mean at each size, but the gap to Any and All at 10,000 elements is small relative to the reported variation.
However, I would lean towards using the implementations with LINQ Any or All because of their simplicity.
You can find the source code for the benchmark on my GitHub, including later contributions with additional scenarios. Feel free to submit a PR with a faster implementation if you can think of one.
Summary
- Use a
HashSetloop when you want to stop at the first duplicate.AnyandAllcan do the same. - Expect O(n) time and O(n) extra space under normal hashing assumptions.
- Count comparisons inspect the full input and may enumerate the source again.
- Measure your actual collection and runtime. Duplicate position changes how much work an early-exit implementation performs.
Thanks for reading.
And stay awesome!
Frequently Asked Questions
How do you check if a collection contains duplicates in C#?
Add each element to a HashSet while iterating: when HashSet.Add returns false, you found a duplicate. You can write this as a foreach loop or more compactly with the LINQ Any or All methods. Comparing the Distinct or ToHashSet count against the total count also works.
What is the fastest way to find duplicates in a collection?
The foreach loop with a HashSet had the lowest mean time in these 2022 benchmarks on integer arrays of 100, 1,000, and 10,000 elements, with one duplicate around 41% of the way through. The Any and All results were close, especially at 10,000 elements. Benchmark your runtime, collection type, and duplicate position before treating one implementation as fastest.
What is the time complexity of checking for duplicates with a HashSet?
Expected time is O(n), with O(n) additional space, assuming well-distributed hashes and constant-time hashing and equality. HashSet.Add is amortized O(1); an individual resize can take O(n). The loop can stop early when it finds a duplicate.
How does HashSet.Add detect duplicates?
HashSet.Add returns false when the element already exists in the set. While looping over a collection and adding every element, the first false return signals a duplicate; completing the loop means every element is unique.
Is comparing Distinct and total counts a good way to check for duplicates?
It works for a stable, repeatable collection, but Distinct must inspect the entire input. The original Count may use a stored collection count or enumerate the input again, depending on its type. A HashSet loop can stop at the first duplicate and only enumerates the input once.